Infinite scrolling loads more content as you move down a page, instead of using traditional pagination. With JavaScript infinite scroll pagination, the page fetches additional batches of content as you scroll. A normal request doesn't scroll, so it only returns the content loaded initially.
In this tutorial, we'll scrape the infinite scroll page on Quotes to Scrape, a practice site for web scraping, from Node.js using ScrapingBee's JavaScript Scenario feature.
First, we request the page without scrolling. Then, we load more content using the scroll_y and infinite_scroll instructions.
Prerequisites
- Node.js 24 or later
- A ScrapingBee API key
You can create a ScrapingBee account and find your API key in the ScrapingBee dashboard.
Create a new project and install the ScrapingBee Node.js SDK:
mkdir infinite-scroll-page-demo
cd infinite-scroll-page-demo
npm init -y
npm install scrapingbee@2
1. Request the Page Without Scrolling
First, request the infinite scroll page without performing any scrolling.
Create index.js and add:
const scrapingbee = require("scrapingbee");
const fs = require("fs");

const OUTPUT_FILE = "page.html";

const PARAMS = {
  wait_for: ".quote",
};

async function scrapePage() {
  const client = new scrapingbee.ScrapingBeeClient("YOUR-API-KEY");

  try {
    const response = await client.htmlApi({
      url: "https://quotes.toscrape.com/scroll",
      params: PARAMS,
      retries: 5,
    });

    const html = new TextDecoder().decode(response.data);
    fs.writeFileSync(OUTPUT_FILE, html);

    const count = (html.match(/class="quote"/g) || []).length;
    console.log(`Saved ${OUTPUT_FILE} (${count} quotes)`);
  } catch (error) {
    const body = error.response
      ? new TextDecoder().decode(error.response.data)
      : "";
    console.error("Error:", error.message, body);
    process.exitCode = 1;
  }
}

scrapePage();
The wait_for: ".quote" tells ScrapingBee to wait until the first quote appears before it returns the page. The page loads its quotes with JavaScript after it opens, so without this setting the response can contain no quotes at all.
Replace YOUR-API-KEY with the API key from your ScrapingBee account.
Run the script:
node index.js
Output:

The plain request returns only the first 10 quotes, because ScrapingBee returned the page as it was before any scrolling.
2. Using the scroll_y Instruction
The scroll_y instruction scrolls the page down by a set number of pixels. Use it when you want to control each scroll yourself.
Replace the contents of index.js with:
const scrapingbee = require("scrapingbee");
const fs = require("fs");

const OUTPUT_FILE = "scrolled-page.html";

const PARAMS = {
  wait_for: ".quote",
  block_resources: false,
  js_scenario: {
    instructions: [
      { scroll_y: 10000 },
      { wait: 2000 },
      { scroll_y: 10000 },
      { wait: 2000 },
    ],
  },
};

async function scrapePage() {
  const client = new scrapingbee.ScrapingBeeClient("YOUR-API-KEY");

  try {
    const response = await client.htmlApi({
      url: "https://quotes.toscrape.com/scroll",
      params: PARAMS,
      retries: 5,
    });

    const html = new TextDecoder().decode(response.data);
    fs.writeFileSync(OUTPUT_FILE, html);

    const count = (html.match(/class="quote"/g) || []).length;
    console.log(`Saved ${OUTPUT_FILE} (${count} quotes)`);
  } catch (error) {
    const body = error.response
      ? new TextDecoder().decode(error.response.data)
      : "";
    console.error("Error:", error.message, body);
    process.exitCode = 1;
  }
}

scrapePage();
block_resources is set to false so ScrapingBee loads the page's CSS and images, which it blocks by default. Without the CSS, the 10 quotes render as a short block that fits inside the browser window, so the page can't scroll and no new batches load. In our tests, the count stayed at 10 until we added this setting.
Run the script:
node index.js
Output:
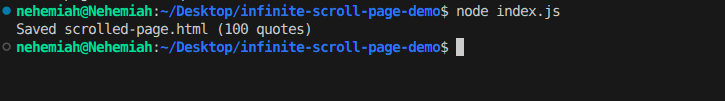
When we ran this script, it returned all 100 quotes on the site. If you get fewer quotes, increase the wait values or add more scroll_y and wait instructions. The whole JavaScript scenario must finish within 40 seconds, so keep the total wait time within that limit.
3. Using the infinite_scroll Instruction
The infinite_scroll instruction scrolls to the bottom of the page repeatedly, pausing between scrolls.
Replace the contents of index.js with:
const scrapingbee = require("scrapingbee");
const fs = require("fs");

const OUTPUT_FILE = "infinite-scroll.html";

const PARAMS = {
  wait_for: ".quote",
  block_resources: false,
  js_scenario: {
    instructions: [
      {
        infinite_scroll: {
          max_count: 3,
          delay: 2000,
        },
      },
    ],
  },
};

async function scrapePage() {
  const client = new scrapingbee.ScrapingBeeClient("YOUR-API-KEY");

  try {
    const response = await client.htmlApi({
      url: "https://quotes.toscrape.com/scroll",
      params: PARAMS,
      retries: 5,
    });

    const html = new TextDecoder().decode(response.data);
    fs.writeFileSync(OUTPUT_FILE, html);

    const count = (html.match(/class="quote"/g) || []).length;
    console.log(`Saved ${OUTPUT_FILE} (${count} quotes)`);
  } catch (error) {
    const body = error.response
      ? new TextDecoder().decode(error.response.data)
      : "";
    console.error("Error:", error.message, body);
    process.exitCode = 1;
  }
}

scrapePage();
In this scenario:
max_countsets the maximum number of scrollsdelaysets the delay between scrolls in milliseconds
Run the script:
node index.js
Output:
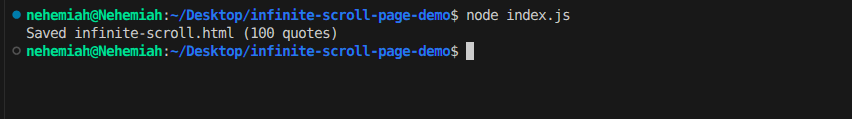
When we ran this script, it returned all 100 quotes. Results can vary with how quickly each batch loads. If you get fewer, increase delay or max_count.